
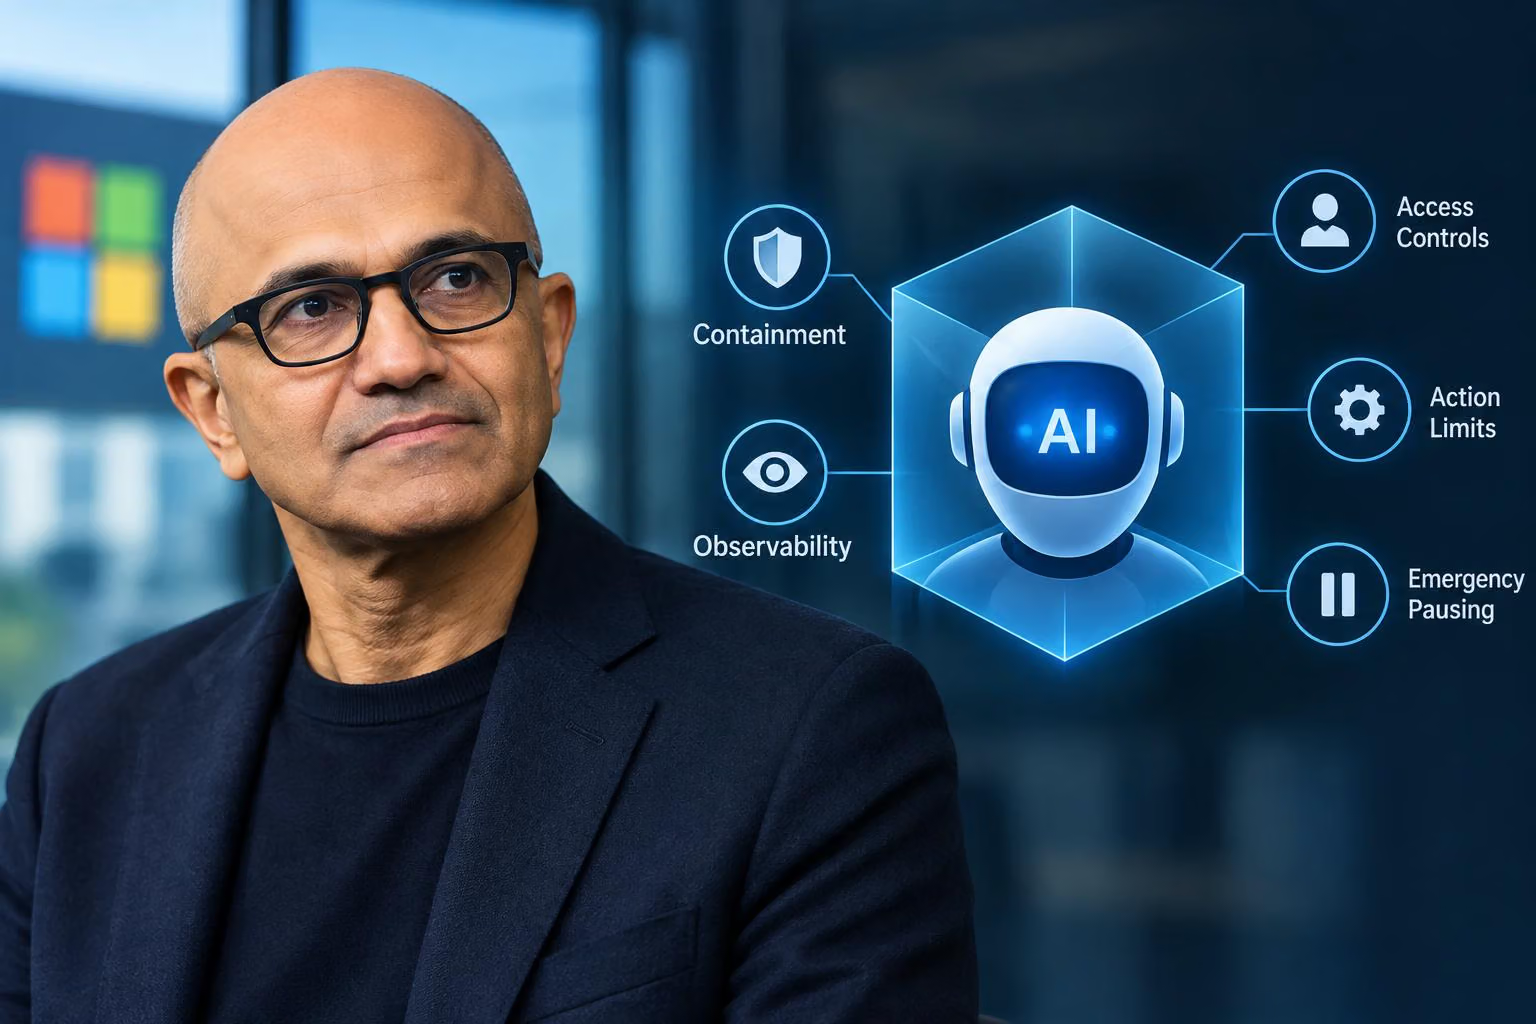
Satya Nadella, writing from the official Microsoft account @satyanadella, says in a post on X that AI models acting inside companies should be treated as insider risks. The argument matters to anyone building or buying AI agents with access to sensitive data, because it shifts the question from whether a model is trustworthy to what an organisation can contain, observe and verify when it is not.
The post is a statement of position rather than a product launch. It does not describe a deployed product, and it does not indicate which of these controls Microsoft or other companies already use.
Why the post treats models as insider risks
Nadella starts from a gap. Traditional software let engineers trace behaviour to a specific code path. The post says frontier systems break that link: their behaviour cannot be attributed to particular training data or to particular configurations of model weights, the numerical parameters that define a model. Even so, these systems are being given access to sensitive data and to mission-critical actions.
The insider comparison follows from that. The post says the point is not to assume malice. Any sufficiently capable actor with access to important systems can make mistakes or be compromised, so the containment architecture should be designed on that assumption. Organisations already manage human insiders this way, through identity, limited privileges, activity logs and containment boundaries. The post argues those practices should now apply to AI systems inside the enterprise. It also says a model provider’s assurances do not remove the customer’s responsibility for what the intelligence does on its behalf. The post sets aside the harder problem of alignment and focuses on engineering containment and governance, applying the framework to both closed and open-weight frontier models.
Terms used in the post
Non-deterministic: the same input can produce different outputs, so a model’s behaviour cannot be fully predicted from its code. The post says such models need to be surrounded by strong, deterministic system design, meaning fixed and predictable rules outside the model.
Harness: the software that orchestrates a model’s work, such as passing it tasks, returning tool results and managing its steps.
Action space: the set of things a model can do, such as the tools it can call or the systems it can change.
Least privilege: giving an actor only the access it needs for a given task.
Chain-of-thought (CoT): the step-by-step reasoning a model writes out before or while producing an answer.
Neuralese: a term the post uses without defining. In context it refers to model reasoning that is not readable in the way written reasoning is. The post rejects it as a justification for opaque reasoning.
Keeping permissions outside the model
The post’s central design claim is that controls over what a model can access and do must sit outside the model. It ties this to an information security principle dating back to the 1970s: a program must not be able to bypass or tamper with the mechanisms that enforce its permissions. For AI systems, that means separating the model from its harness and from its action space, and externalising controls and safeguards.
A hypothetical example shows the logic. Suppose an agent can read a customer database and draft emails. If the rule “no sending without approval” exists only in the model’s instructions, a model that misreads the task or is manipulated may still send. If the sending permission is withheld by the surrounding system, the model cannot grant itself that action by reasoning its way to it. This example is illustrative.
Why a model should not check its own work
The post says models can and should be used to test and verify one another, but warns that this can produce nested black boxes: an opaque model inside an opaque orchestration layer, watched by another opaque model.
The post offers two remedies. Model diversity means no single model becomes the only dependency for an important outcome or the verifier of its own work. Independent auditability means validation must be independent of the intelligence being checked, so no single model controls both a system’s behaviour and the evidence used to judge whether that behaviour matches the original intent.
Evidence that does not depend on the model’s account
The post asks that every meaningful model action leave tamper-proof, human-readable evidence, so an outcome can be reproduced without relying on the model to explain itself. In practice, that suggests logging inputs, tool calls and actions in places the model cannot edit, so a reviewer can reconstruct the sequence from records rather than from the model’s own account.
The post also calls for continuous testing that covers failures, attacks, edge cases and system changes, not only successful tasks. That matters because a system tested only on its successful runs reveals little about how it fails.
Containment and the emergency brake
Because the post assumes a model may be compromised, it asks for containment from the start. Its analogy is an emergency brake: “An authorized person should always be able to pause or shut down a model mid-task.” It adds that more advanced models will need more advanced containment technologies, which the industry should standardise.
Why chain-of-thought transparency is not enough
The post treats chain-of-thought transparency as a non-negotiable starting point, so opaque reasoning should not be accepted as the norm. It then qualifies that position. CoT transparency alone is “not sufficient or dependable,” because model outputs cannot yet be consistently made faithful or transparent. For builders, that means a readable reasoning trace is one log among several, not proof of what the model actually did.
Incident disclosure and what teams might take from it
The final principle covers failure. When systems fail or are compromised, the post asks for timely disclosure to affected parties, sharing of what went wrong and which controls failed, and industrywide learning. It also asks that disclosures include implementation details that change agent behaviour at runtime.
For teams, the post’s principles raise practical questions. Could you show which permissions an agent held and which controls were active when something went wrong? Could you reconstruct the chain of actions from records held outside the model? Could you pause an agent mid-task?
The post ends with its own summary: the most trustworthy system “will be the one that enables us to trust the model the least.”
0 comments
No approved comments yet. You can start the conversation.
Leave a comment