
I've spent a few hours testing Claude Opus 5.5, and it's already the best AI model I've used for coding. It's still early, but its speed, coding quality and overall feel have stood out so far. I'll update this review as I spend more time with it.
Claude Opus 5.5 speed
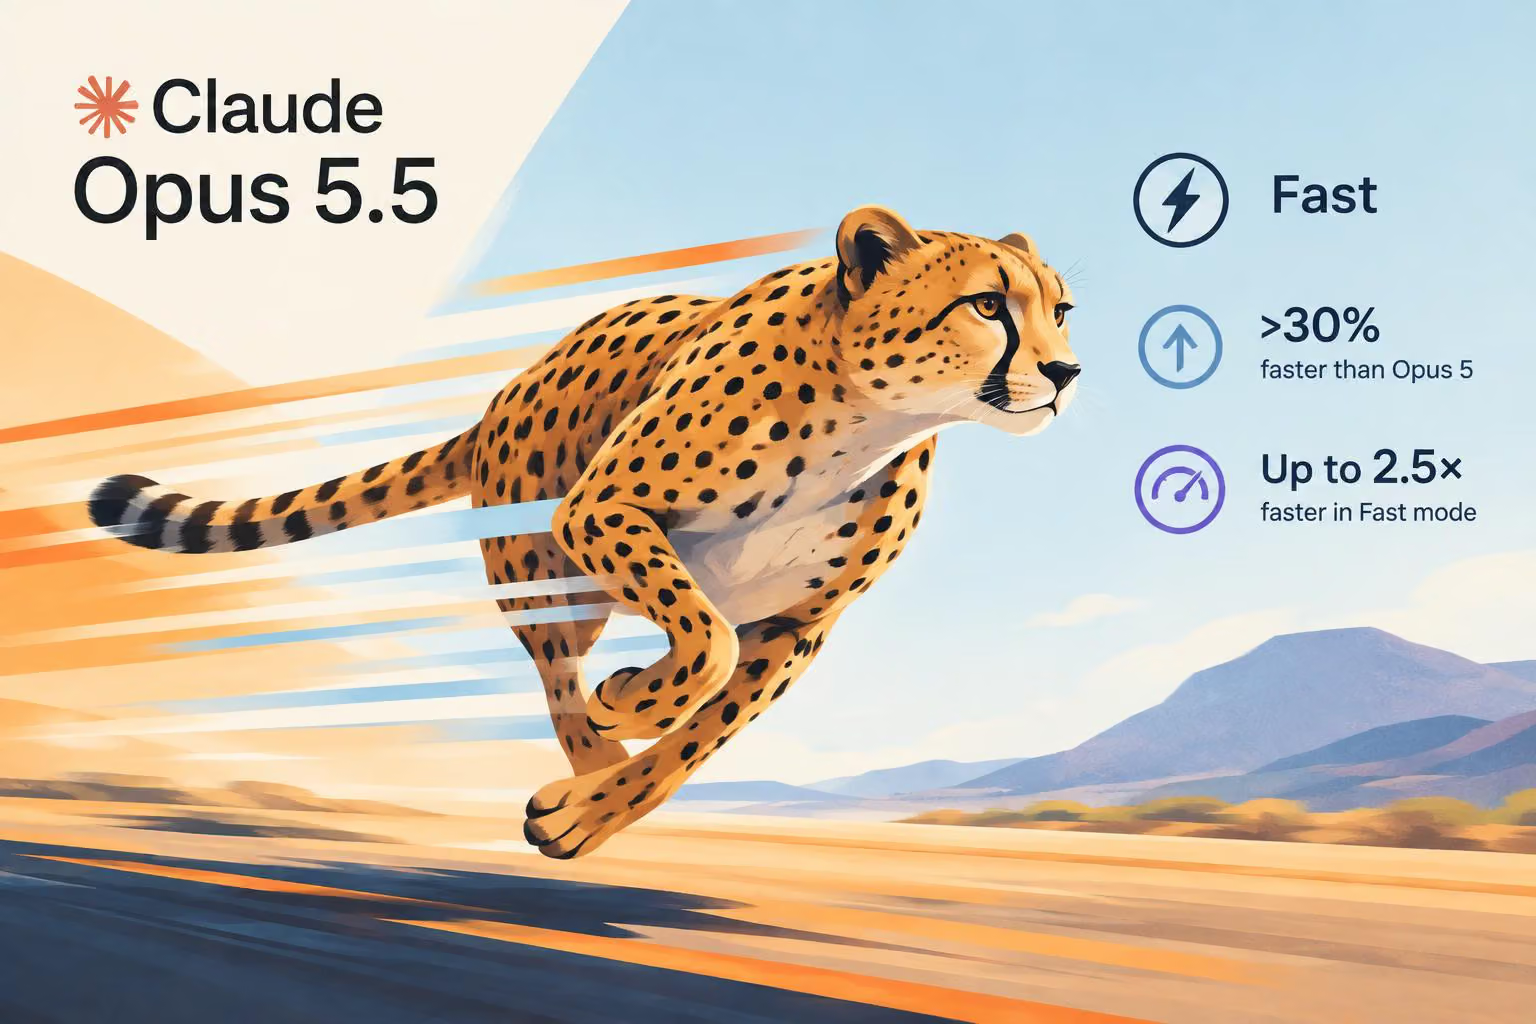
Opus 5.5 feels fast. Responses come back quickly enough that it no longer feels like I'm waiting on a flagship model, and it has kept that pace across longer sessions.
For context, Anthropic says Opus 5.5 generates output more than 30% faster than Opus 5. Its separate Fast mode is advertised as up to 2.5 times faster in Claude Code and on the Claude Platform. That's a different setting from the standard speed I'm describing here. Anthropic's release announcement
Claude Opus 5.5 pricing
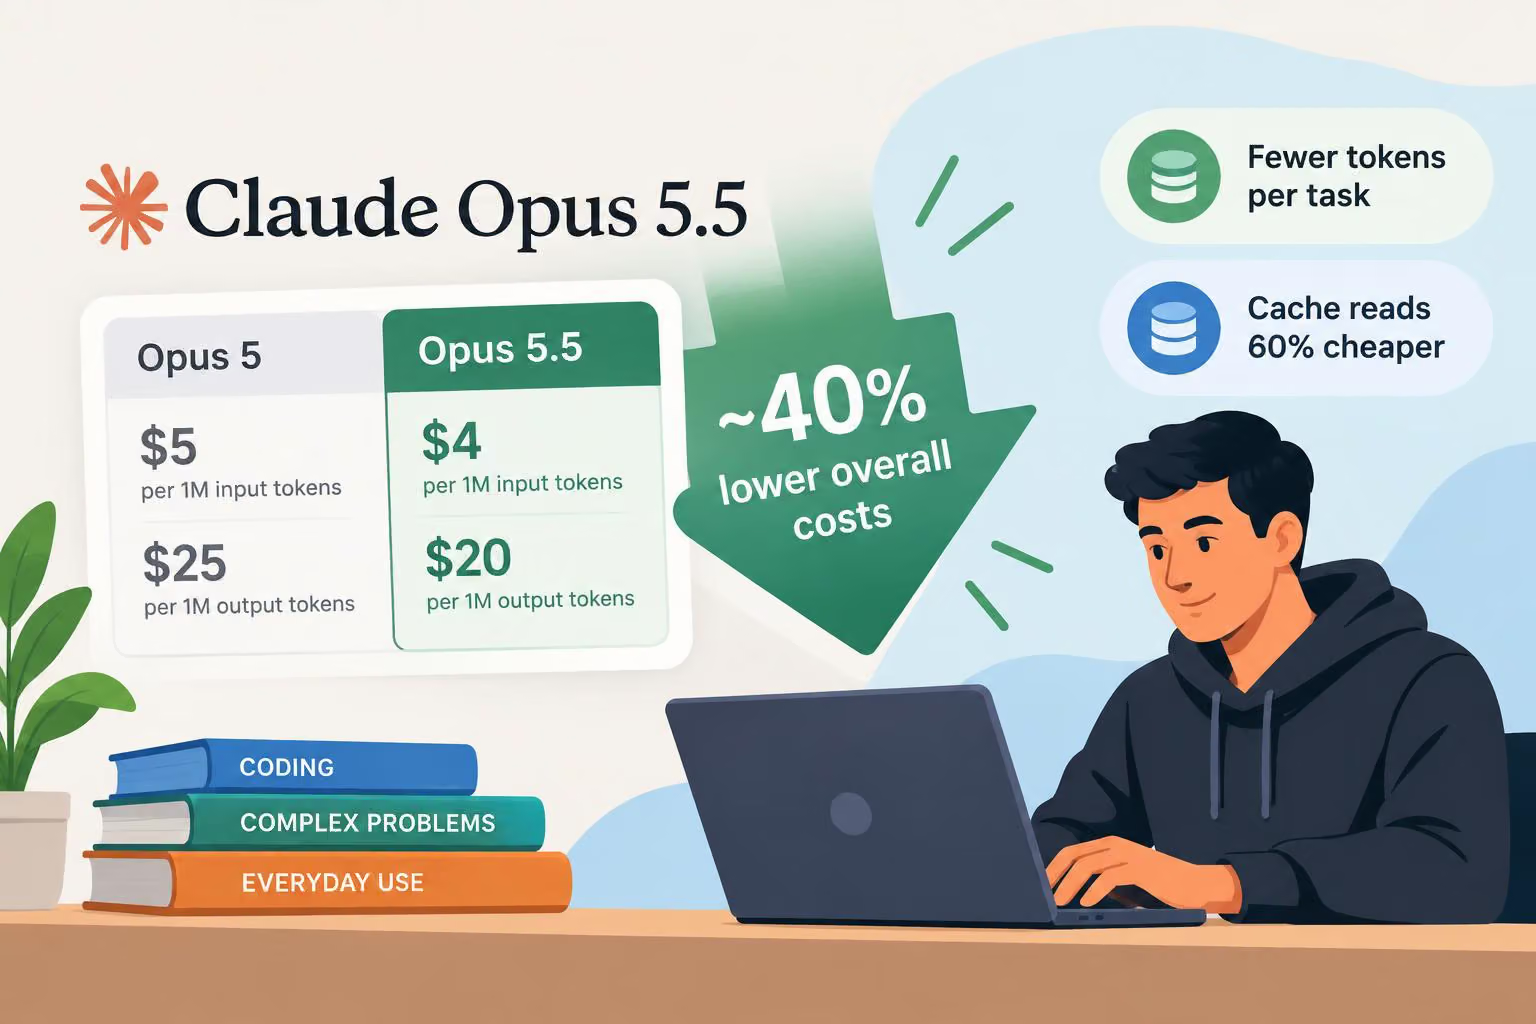
The lower price is a big deal. For API use, Opus 5.5 costs $4 per million input tokens and $20 per million output tokens, down from $5 and $25 for Opus 5. Anthropic estimates typical workloads will cost about 40% less overall because Opus 5.5 also uses fewer tokens per task. Cache reads are 60% cheaper.
That makes Opus 5.5 more practical for everyday coding, as well as difficult problems.
Opus 5.5 for coding: back end, front end and game development
I've tested Claude Opus 5.5 across back-end logic, front-end UI and game development, and it's performed well in all three so far. I haven't found an obvious weak area yet.
The standout has been 3D game development. Opus 5.5 has produced polished, working 3D scenes quickly, with far less back-and-forth than I've needed with earlier models. I can describe what I want loosely, and it usually fills in the gaps sensibly.
That lines up with one detail from the release: Anthropic says that, in an internal test where models built a game from a single prompt, Opus 5.5 scored highest for graphics and polish.
Anthropic also reports 66.4% on Terminal-Bench 4.0, 54.4% on FrontierCode v1.1 and 57.8% on CursorBench 4.0. These are Anthropic's own benchmark results. Anthropic says its results used maximum adaptive-thinking effort, with xhigh effort for Terminal-Bench, so I see them as useful context alongside my hands-on testing rather than a guarantee of what every user will get.
Opus 5.5 vs Fable and Astra
In the coding tasks I've tried so far, I found Claude Opus 5.5 stronger than both Fable and Astra.
Claude usage limits: finally fixed
Usage limits have been one of the biggest frustrations for people using Claude heavily. Anthropic says it is increasing the five-hour limits for Pro, Max, Team and seat-based Enterprise plans. Subscribers can also save a rate-limit reset and use it when they choose.
On the Claude Max 5x plan, I got five hours of solid work out of Opus 5.5 before hitting a limit. That's a big improvement in my experience, and so far it feels like Anthropic has made a real difference here.
Early verdict: is Claude Opus 5.5 worth it?
Based on my first few hours with it, yes. This is still an early review, and I haven't tested Opus 5.5 on larger codebases or long-running projects, where problems can take longer to show up. Even so, speed, pricing, coding quality and usage limits have all improved in one release.
Early rating: 9/10.
0 comments
No approved comments yet. You can start the conversation.
Leave a comment