
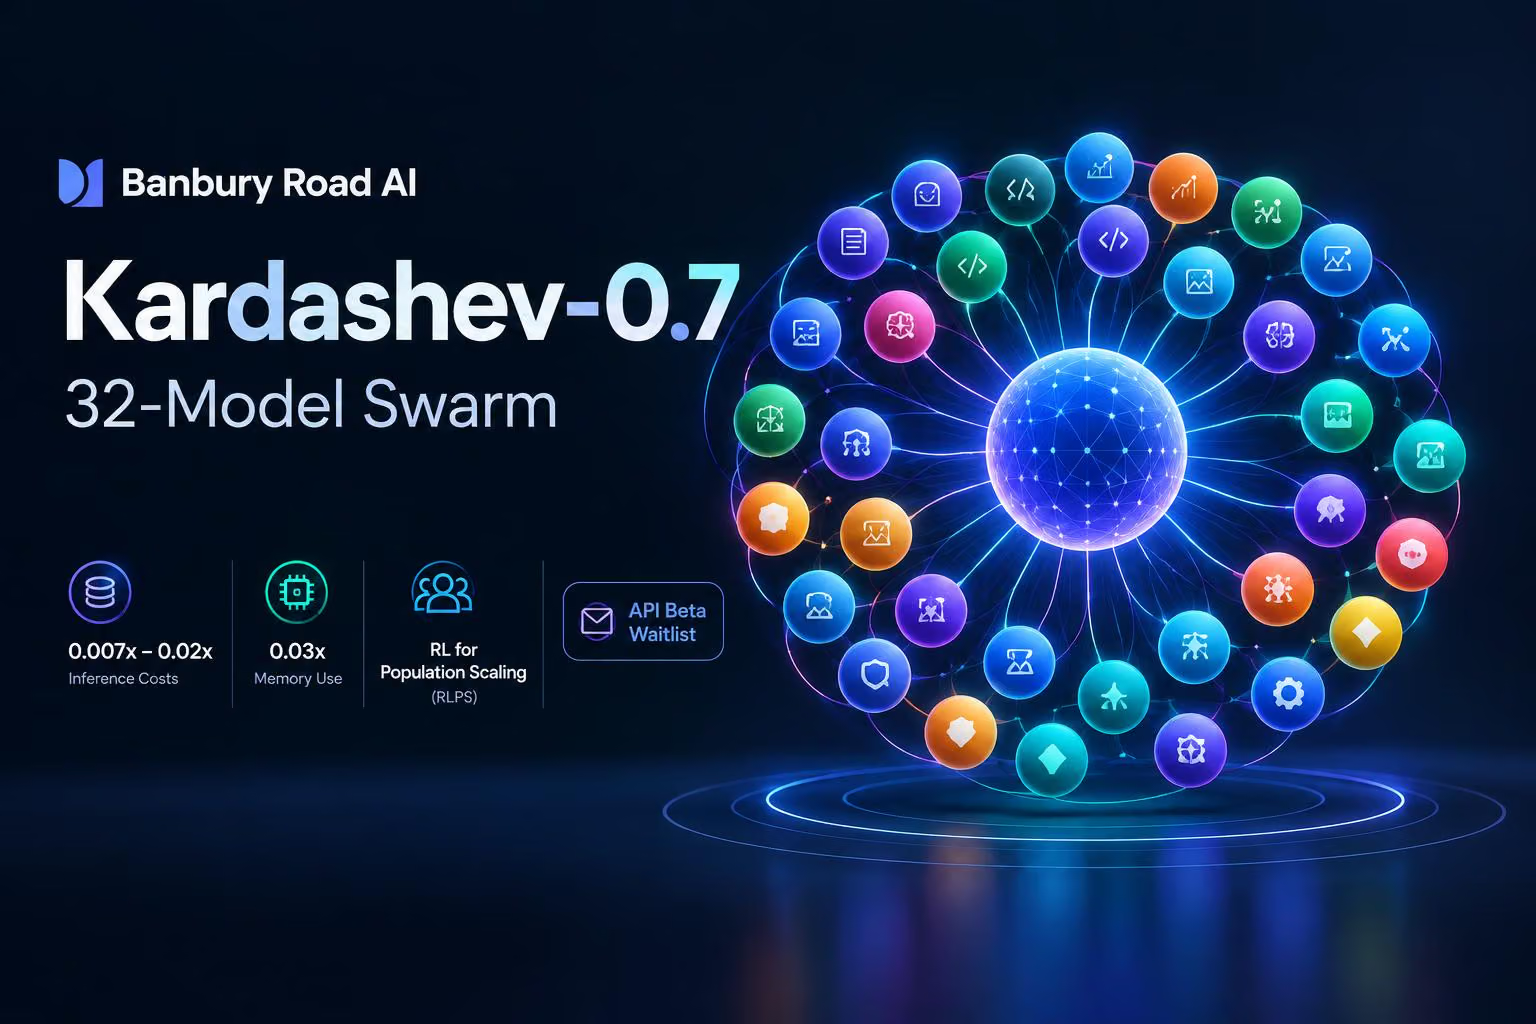
The Kardashev-0.7 model swarm is a system of 32 distinct AI models that, according to an October 5, 2026 post on X, was trained so the models develop complementary skills. The post, from engineer cat (@MLCatttt), whose profile lists Banbury Road AI, calls it "the world's first trained swarm made of 32 distinct models" and says it delivers frontier performance at 0.007x to 0.02x of the inference cost and 0.03x of the required memory.
Those figures are ratios against a baseline the post never names, and it offers no benchmark results to test them. The more useful question is the idea underneath: whether intelligence can grow by adding specialized models instead of making one model larger.
How the Kardashev-0.7 model swarm is trained with RLPS
The post names the method RL for Population Scaling (RLPS). Reinforcement learning (RL) is a training approach in which a system adjusts its behavior using feedback, and the "population" in the name points to training many models at once. The post does not define the objective or describe the training procedure. A flash report on KuCoin says earlier RLPS work topped out at 16 models, which would make 32 a doubling. That report is short, and the post does not mention the 16-model figure, so treat it as secondary.
What the 0.007x and 0.03x ratios really mean
The post gives inference cost as 0.007x to 0.02x and memory as 0.03x, all relative to an unnamed reference. Read literally, 0.02x means one-fiftieth of the reference cost, and 0.007x means about 1/143. The memory ratio is the more striking figure. If 32 models together need about a thirtieth of the reference's memory, either each model is small or only some are loaded at any moment, and the post does not say which. Two more questions matter: whether the ratio counts the cost of coordinating many models per request, and whether quality holds on the tasks users actually run. The post describes "frontier performance" but gives no score to show it.
Is scaling by model count actually new?
Not entirely. Mixture-of-experts models already route work between specialist sub-networks inside one model, and ensembles combine the answers of several models. The post's claim is narrower: that distinct models trained under RLPS develop complementary roles organically. If specialization really emerges that way at scale, it would suggest that a population of models can be trained to divide labor rather than having the division designed by hand. For developers, the practical stake is whether a cheaper population can replace a single large model for some workloads. That is the result worth watching, and the post offers no published evidence for it yet.
What is still undisclosed, and can you try it?
The post does not explain how tasks reach individual models, how they are coordinated, or how their outputs are merged, so it is unclear whether all 32 run on each query. Live use, the KuCoin report notes, offers no answer key, and the company has not described how the system chooses a response. Access is by joining a waitlist for an API beta at banburyroad.ai, and the post gives no start date, pricing or admission rules. A third-party tools directory describes Banbury Road as a multi-agent research lab based in San Francisco with three employees.
Key takeaways
- The post says the Kardashev-0.7 model swarm uses 32 distinct models trained under RLPS to develop complementary capabilities.
- Its cost and memory ratios are self-reported, use an unnamed baseline and come with no published benchmarks.
- Routing, answer selection and launch timing are undisclosed, so independent testing and a technical write-up are the real tests.
Frequently asked questions
What is the Kardashev-0.7 model swarm?
It is a group of 32 distinct models that the post says were trained with RLPS to develop complementary capabilities, presented as a way to scale AI by model count.
Does the swarm run all 32 models for every query?
The post does not say, and it does not describe how tasks are routed or how answers are selected.
Can I use Kardashev-0.7 now?
Access is through a waitlist for an API beta, and the post gives no start date or pricing.
0 comments
No approved comments yet. You can start the conversation.
Leave a comment