
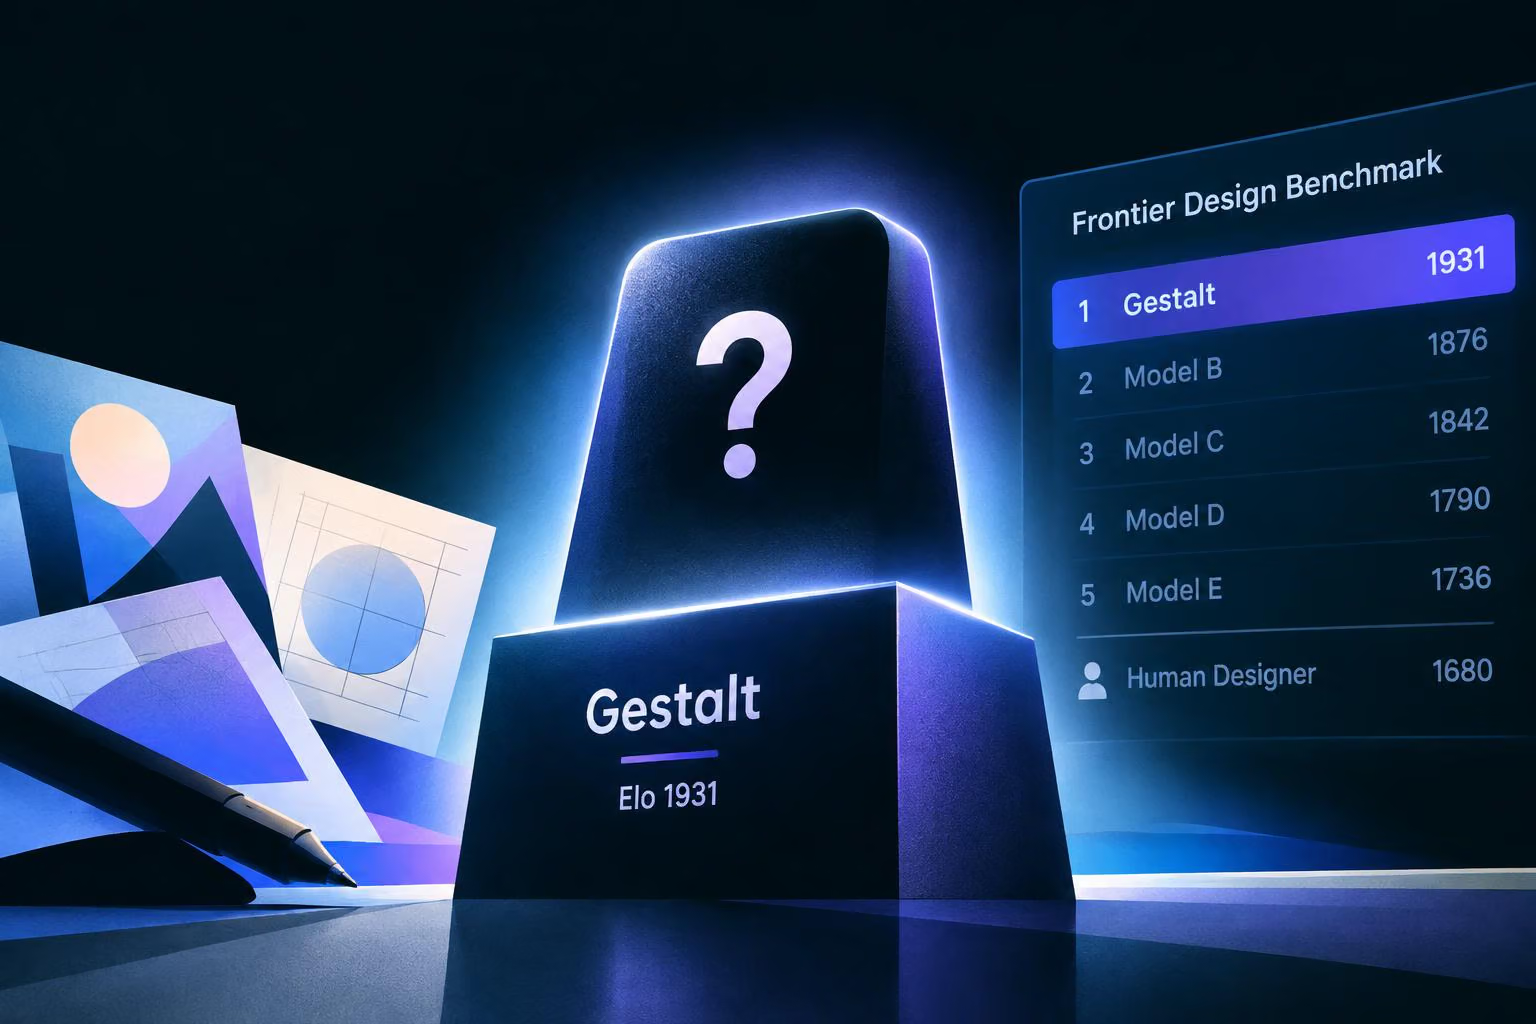
The Gestalt stealth model, whose developer has not been named, now ranks first on Contra Labs' new Frontier Design Benchmark. Its score sits above every named model and above the human designer baseline. Nobody has said whose model it is, so claims about its origin remain unconfirmed.
The sighting was flagged on X by @notjazii, who says the model is "mogging every model available" and relays a rumour that it could be Anthropic's next model, held back until after an IPO. The author says they are unsure of the rumour and had no hands-on access, with only leaderboard figures and sample outputs to go on.
What the design leaderboard shows about Gestalt
BenchFlow helped build Contra Labs' Frontier Design Benchmark, which ranks models with Elo, a rating derived from head-to-head votes. More than 4,300 blind votes feed the leaderboard, cast by 35 designers on briefs drawn from real client work on Contra's marketplace.
Gestalt ranks first on 1931 Elo, winning 90% of comparisons, with a 95% confidence interval from 86 to 92. The human golden designs are second at 1739 and 74%, and the best named model, Claude Fable 5.2, sits at 1713. Gestalt leads the human golden designs by about 190 points.

Media source: x.com
Who made the Gestalt stealth model?
No developer has been named, and the leaderboard row gives none. The top rows do name their labs, such as Anthropic for Claude Fable 5.2, OpenAI for GPT-6.1 Sol and Alibaba for Qwen3.8 Max. The Anthropic rumour is speculation. One summary of the post ties the guess to the ticker ANT, which starts trading that day, but nothing confirms the link.
The thread's guess names "fable 5.5", but the leaderboard lists Claude Fable 5.2, so the guess points to a version the board does not show. One census of OpenRouter's stealth models found seven of thirteen had been revealed, each through the lab's or platform's own channel. Not every stealth entry is a big-lab model: Union Alpha, which beat GPT-5.6 Sol on a coding benchmark, was later identified as Pareto 26.9 from @TheUnbiasedCo.
How far can the ranking be trusted?
The method has real strengths. Votes are blind and come from professional designers, and Contra reports that its rubric scores track designer ratings closely (r = 0.94). The limits are real too. This is one company's benchmark, built on 33 tasks whose outputs are finished websites. Vote totals also differ: one summary cites 3,591 votes, while the leaderboard shows 4,311. Contra's own launch message says "Designers are still better", so a win on this board is a win on these briefs, not proof that design is solved.
Why it matters: if the ranking holds, blind judges preferred this model's sites to the human golden designs on these briefs. That would matter to freelancers and studios that sell site design, who would have to show what their work adds. The board reports votes on output, not cost, speed or how well a model takes feedback, so it cannot settle which tool is worth buying.
What would confirm or disprove the claim
An official launch or naming by the developer, which would settle the origin question.
Public access through an API or arena, so outside testers can check outputs against the claims.
Independent reruns of the design comparisons that reproduce a lead of this size.
A denial from any lab named as a candidate, which would weaken the Anthropic link.
Key takeaways
Gestalt tops Contra's design leaderboard at 1931 Elo, about 190 points above the human golden designs, but its developer is unnamed.
Stealth models are not always big-lab models, so the Anthropic guess needs evidence the post does not supply.
Treat the ranking as promising but narrow: one vendor, 33 tasks, and no hands-on testing yet.
Frequently asked questions
Who made the Gestalt stealth model?
No developer has been named. The Anthropic link is a rumour, and no company has confirmed it.
Does Gestalt really beat human designers?
On Contra's leaderboard, yes: Elo 1931 against 1739 for the human golden designs. That result comes from one benchmark and has not been independently confirmed.
Can anyone test Gestalt yet?
Not so far, according to the post's author, who could not run it.
0 comments
No approved comments yet. You can start the conversation.
Leave a comment