
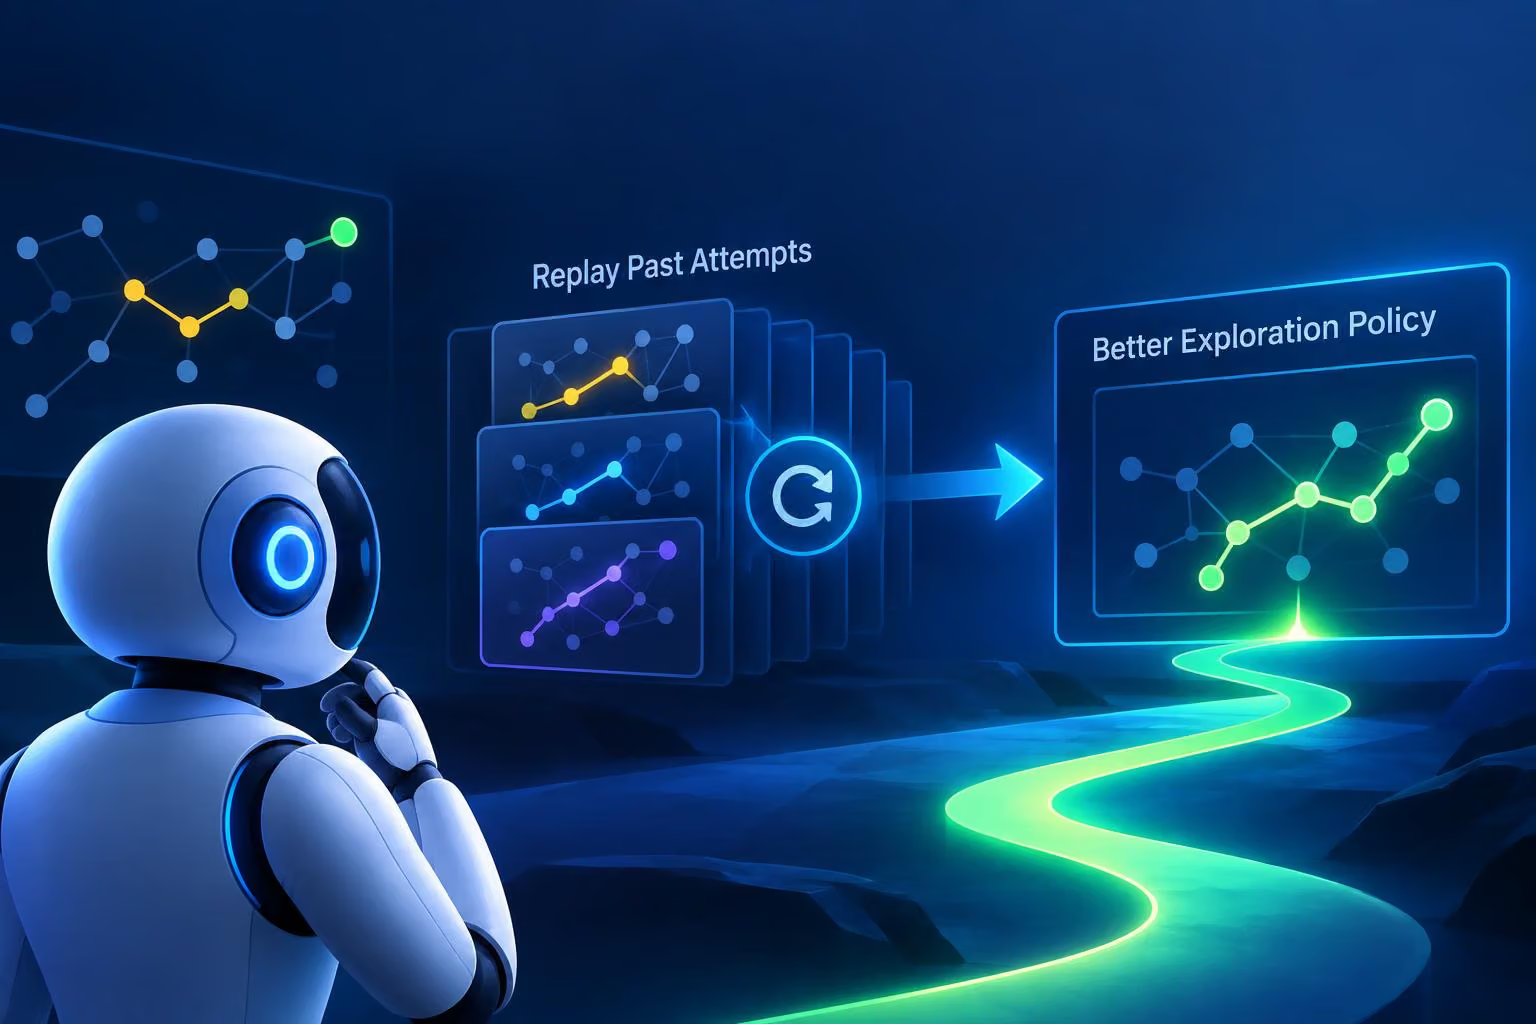
In a post on X, @Dr_Singularity says Google/DeepMind researchers have introduced Dream-RSI, a system that improves how an AI agent searches for solutions by replaying its previous discovery attempts. The described approach tests alternative exploration strategies in a replay simulator, then deploys a better-performing policy in later discovery rounds.
The post says Dream-RSI matched or improved discovery quality in algorithm design, mathematical optimization and GPU kernel engineering while reducing agent calls by up to 162 times in one setting. It also emphasizes that the system changes the agent’s exploration policy rather than its underlying model weights. The post does not identify which setting produced the 162-times reduction.
Dream-RSI is an exploration layer around an existing agent
The visible paper excerpt describes Dream-RSI as a lightweight orchestration layer around an unchanged coding agent. In this context, an exploration policy is the strategy that determines how an agent searches through possible approaches: which branch to pursue, how to use earlier discoveries and how to allocate further attempts.
Rather than asking the underlying agent to improve its neural-network weights, Dream-RSI uses the record of earlier discovery work to improve that search strategy. The system’s recursive loop is therefore at the policy level: past searches help produce a better policy, and that policy guides new searches whose results can feed the next round.
System element | Role |
|---|---|
Underlying coding agent | Remains unchanged |
Exploration policy | Is evaluated, refined and redeployed in later discovery rounds |
Historical discovery attempts or trees | Provide the record for replay |
Replay simulator | Tests alternative strategies and supplies lower-cost feedback |
Subsequent discovery | Uses the improved policy for further searches |
How the replay-based loop works
Dream-RSI starts with accumulated discovery attempts, described in the visible paper excerpt as historical discovery trees. It constructs a replay simulator from those records. Within that simulator, alternative exploration policies can be evaluated without invoking repetitive online evaluations.
The post says the system can test thousands of alternative strategies cheaply. The paper excerpt describes the replay process as providing low-cost, off-policy feedback: information used to evaluate a different strategy from the one that originally generated the recorded search. This lets Dream-RSI refine its exploration policy before redeploying it for online discovery.
New searches then expand the available history, giving the system more material for another replay-and-refinement cycle. The reported improvement comes from changing how the agent navigates a search space, not from describing a new foundation model or a weight-training procedure.
Where the reported system was applied
The post names three application areas: algorithm design, mathematical optimization and GPU kernel engineering. They represent different kinds of discovery problems, but the available source material does not provide task-level examples or enough detail to compare their individual results.
Algorithm design: the system is described as helping an agent explore possible algorithmic solutions.
Mathematical optimization: the reported application concerns searching for effective solutions in optimization problems.
GPU kernel engineering: the system is also described as supporting discovery in the design or improvement of GPU kernels.
Across these areas, the post says Dream-RSI matched or improved discovery quality while substantially reducing discovery cost in several settings. That is a reported cross-application result, not evidence that every task receives the same improvement.
What “recursive self-improvement” means here
In Dream-RSI’s described design, “recursive” refers to the repeated use of discovery history to improve the policy that controls future discovery. A first round produces a record of searches. Replay evaluates alternative ways to explore that record. The resulting policy is then used in another round, producing more history for later refinement.
The coding agent remains unchanged while Dream-RSI improves the exploration policy rather than the model weights. The system can therefore become better at allocating search effort without implying that it has created a new foundation model or autonomously rewritten its own learned parameters.
Nor does the term by itself establish general-purpose self-improvement or artificial general intelligence. It describes the scope of the reported loop: improving an exploration strategy within the discovery settings discussed by the source.
How to interpret the reported efficiency result
The post reports that Dream-RSI reduced agent calls by up to 162 times in one setting while matching or improving discovery quality. Fewer agent calls may reduce one component of discovery cost, particularly if online evaluations are more resource-intensive than replay-based policy checks. The paper excerpt presents replay as a way to avoid repetitive online evaluations, but it does not provide a full cost breakdown.
The post does not identify the setting associated with the 162-times figure, define exactly how agent calls were counted or name the baseline. The number should therefore be read as an attributed result for a particular setting—not as a universal reduction in the total cost of AI discovery.
More broadly, the mechanism suggests that replay-based policy evaluation may be useful when historical discovery records provide informative feedback about alternative strategies. The available description does not explain how Dream-RSI handles failures or shifts in the search distribution, so those questions remain open.
Dream-RSI’s reported contribution is consequently narrower and more concrete than a claim that an AI has become generally self-improving. It is a framework for repeatedly refining an agent’s exploration policy from its discovery history while leaving the underlying coding agent unchanged.
0 comments
No approved comments yet. You can start the conversation.
Leave a comment